変換する PDF 編集可能 PDF 使用 OCR 使用 n8n アクション
PDF4me 変換する PDF 編集可能 PDF 使用 OCR スキャンされた変換 PDF画像ベースのドキュメントを検索可能、編集可能な形式に変換します。 PDFs を通じて n8n 自動化ワークフロー。プロセス PDF離れて n8n トリガー、バイナリデータ、base64文字列、または公開 URL適用する OCR 多言語対応、品質レベル選択(ドラフト/高)、条件付きテクノロジー OCR 処理、テキスト レイヤーの作成、レイアウトの保持、検索可能なコンテンツの生成。このソリューションは、文書のデジタル化、スキャンされた文書の処理、請求書に最適です。 OCRアーカイブ変換、検索可能 PDF 作成、および自動化 OCR 書式を維持したまま正確なテキスト認識を行い、シームレスな統合を実現するワークフロー。
設定
追加する PDF4me "変換する PDF 編集可能 PDF 使用 OCR「ノードをあなたの n8n ワークフローを実行し、必要なパラメータを設定します。初期設定手順については、こちらをご覧ください。 n8n 統合ガイド。
前提条件:
- PDF4me API 資格
- n8n ワークフローへのアクセス
構成:
- 追加 PDF4me ノードからワークフローへ
- 「変換」を選択してください PDF 編集可能 PDF 使用 OCR" アクション
- 入力パラメータを設定します(下記参照)。
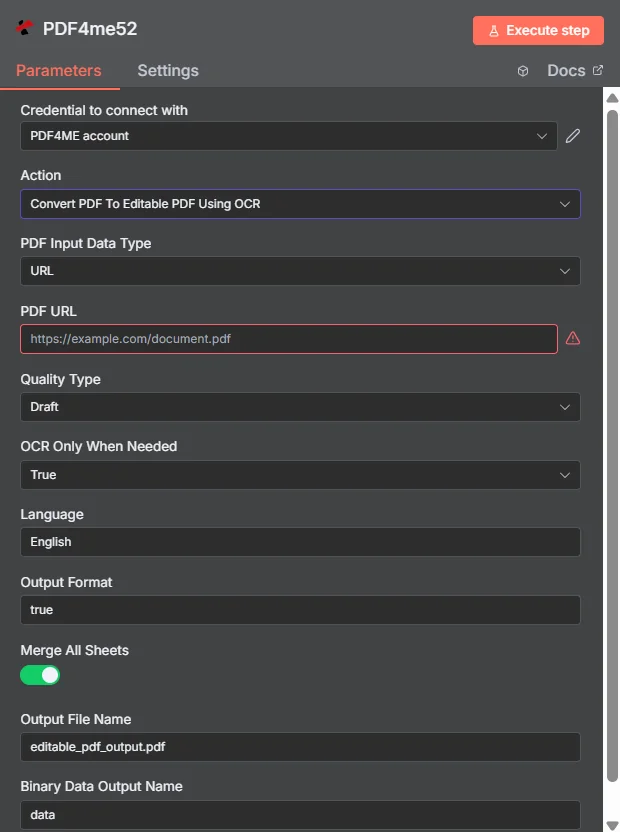
パラメータ
Convertのパラメータ一覧 PDF 編集可能 PDF 使用 OCR アクション。これらのパラメーターを設定して制御します。 OCR 変換。
重要: アスタリスク(***)が付いているパラメータは必須であり、アクションが正しく機能するためには必ず指定する必要があります。
| パラメータ | 必須 | その機能 | 例 |
|---|---|---|---|
| PDF Input Data Type | Required | Choose how to provide the PDF file. Options: Binary Data, Base64 String, URL. Default is `Binary Data`. | Binary Data |
| PDF Binary Field | Conditional | Name of the binary property that contains the PDF file. Shown when PDF Input Data Type is Binary Data. Default is `data`. | data |
| PDF Base64 Content | Conditional | Base64 encoded PDF content. Shown when PDF Input Data Type is Base64 String. | JVBE... |
| PDF URL | Conditional | URL to the PDF file. Shown when PDF Input Data Type is URL. | https://abc.com/scanned.pdf |
| Quality Type | Required | Choose the quality type for OCR processing. Options: Draft, High. Default is `Draft`. | Draft |
| OCR Only When Needed | Required | Whether to skip recognition when the text is already searchable (True) or always run OCR (False). Options: True, False. Default is `Yes`. | Yes |
| Language | Optional | Language of the text in the source file. Only use if output is not recognizable. Default is `English`. | English |
| Output Format | Required | Text value sent to PDF4me as outputFormat (default `true`). The node always returns a PDF. Default is `Yes`. | Yes |
| Merge All Sheets | Optional | Value sent to PDF4me as mergeAllSheets. The node always returns a PDF. Default is `Yes`. | Yes |
| Output File Name | Optional | Name for the output editable PDF file. Default is `editable_pdf_output.pdf`. | editable_pdf_output.pdf |
| Binary Data Output Name | Optional | Custom name for the binary data in n8n output. Default is `data`. | data |
出力
出力パラメータ
| 分野 | タイプ | 内容物 |
|---|---|---|
success | Boolean | True when the operation succeeded. |
message | String | Status message, `PDF converted to editable PDF using OCR successfully`. |
fileName | String | File name of the resulting file. |
mimeType | String | MIME type of the resulting file, for example `application/pdf`. |
fileSize | Number | Size of the resulting file in bytes. |
qualityType | String | Quality Type that was used. |
ocrWhenNeeded | String | Value of OCR Only When Needed that was sent, as text (`true` or `false`); it does not tell whether OCR was actually run. |
language | String | Language that was sent, or `Not specified` when the field was empty. |
mergeAllSheets | String | Value of Merge All Sheets that was sent. |
data | Binary | The editable (searchable) PDF. |
N8N 行動対応
の PDF4me 変換する PDF 編集可能 PDF 使用 OCR API 複数の形式で表示可能なレスポンスを返します。ニーズに最適な表示形式を選択してください。
- JSON
- Table
- Schema
- Binary
JSON 回答形式
生 JSON からの応答 API:
{
  "success": true,
  "message": "PDF converted to editable PDF using OCR successfully",
  "fileName": "editable_pdf_output.pdf",
  "mimeType": "application/pdf",
  "fileSize": 121875,
  "qualityType": "Draft",
  "ocrWhenNeeded": "true",
  "language": "English",
  "mergeAllSheets": false
}
テーブルビュー
構造化された表形式の応答データ:
| パラメータ | 価値 |
|---|---|
| success | true |
| message | PDF 編集可能に変換 PDF 使用 OCR 成功 |
| fileName | editable_pdf_output.pdf |
| mimeType | application/pdf |
| fileSize | 121875 |
| qualityType | Draft |
| ocrWhenNeeded | true |
| language | English |
| mergeAllSheets | false |
スキーマビュー
レスポンスのデータ構造と型:
success: ✓ true
message: AB PDF converted to editable PDF using OCR successfully
fileName: AB editable_pdf_output.pdf
mimeType: AB application/pdf
fileSize: # 121875
qualityType: AB Draft
ocrWhenNeeded: AB true
language: AB English
mergeAllSheets: ✓ false
タイプ指標:
AB= String#= 番号✓= Boolean
バイナリデータビュー
実際の編集可能な PDF ファイルデータとメタデータ:
data
─────────────────────────────────────────
File Name: editable_pdf_output.pdf
File Extension: pdf
Mime Type: application/pdf
File Size: 119.0 KB
ユースケース
文書のデジタル化とアーカイブ化
- 紙文書やスキャンしたファイルを、検索・編集可能なデジタル形式に変換します。
- 歴史的アーカイブや遺産文書をデジタル化し、現代におけるアクセスと保存を可能にする
- 紙の書類や文書を編集可能なデジタル版に変換します。
コンテンツ管理と検索性
- スキャンした文書をコンテンツ管理システムで検索可能にする
- これまで検索できなかった文書に対して全文検索機能を有効にする
- 画像ベースの変換 PDFユーザーエクスペリエンス向上のため、アクセスしやすく編集可能なコンテンツに変換する
ワークフローの自動化と処理
- 文書処理ワークフローにおけるスキャン文書の変換を自動化する
- 受信した紙文書を処理し、自動データ抽出と分析を行う。
- 以前は静的だったドキュメントコンテンツの下流処理を有効にする