Get Document from PDF4me in n8n
Get Document From Pdf4me is a PDF4me node action in n8n that retrieves a document PDF4me already holds. Use it to collect the result of an earlier processing step, pull a stored file back into a later workflow run, or finish a callback-based job by fetching what was produced.
What this node does
PDF4me: Get Document From Pdf4me is a retrieval utility, not a transformation. It takes just two inputs, a File Name and a Callback URL, and both are required. It returns the stored file unchanged along with its name, size, and MIME type, so anything you need done to the document happens in a separate action chained after it.
Authenticating Your API Request
Every PDF4me node in n8n requires a valid Credential to connect with. Create or select one that holds your PDF4me API key so the workflow can authenticate retrieval requests securely.
Important Facts You Should Not Miss
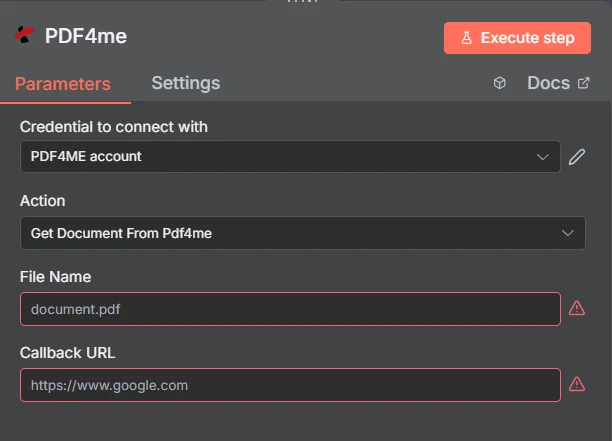
The whole panel is four fields. The red borders on File Name and Callback URL are the node telling you both must be filled in before it will execute.
Retrieval vs Processing Actions
| Question | Get Document From Pdf4me | A processing action |
|---|---|---|
| What it needs | A file name and a callback URL | A source file plus operation settings |
| What it changes | Nothing, the file is returned as stored | The document content or format |
| Where it sits | After the work, to collect the result | In the middle, doing the work |
| What comes back | The stored file plus its metadata | A newly produced document |
| Typical use | Finishing a callback-based job | Converting, securing, or editing |
What Parameters Does Get Document From Pdf4me Need?
| Parameter | Required | What it does | Example |
|---|---|---|---|
| Credential to connect with | Required | The PDF4me account credential the node authenticates with. | PDF4ME account |
| Action | Required | The action this node performs. Select Get Document From Pdf4me. | Get Document From Pdf4me |
| File Name | Required | Exact name of the document to retrieve, including its extension. Best supplied by an expression carrying the name from the producing step. | document.pdf |
| Callback URL | Required | Reachable URL used for callback-based retrieval. The node shows a validation warning until it is set. | https://example.com/callback |
This node has an unusually small surface. There is no input-type selector, no output naming field, and no advanced options collection, which is why every parameter above is marked required rather than conditional.
Output
| Field | Type | What it contains |
|---|---|---|
| success | Boolean | Whether the retrieval request completed. Branch on this before using the file. |
| message | String | Human-readable status text, including error detail when something went wrong. |
| fileName | String | Name of the retrieved document. |
| mimeType | String | Content type of the retrieved file, which tells you what you actually got back. |
| fileSize | Number | Size of the retrieved document in bytes. |
| docName | String | Document name reference, matching fileName. |
| retrievalCompleted | Boolean | Confirmation that retrieval finished. Worth checking alongside success. |
The document itself is returned as binary data alongside these fields, ready to write to storage, attach to an email, or pass into another PDF4me action.
How Do I Set Up Get Document From Pdf4me in n8n?
- Add the PDF4me node to your workflow and set Action to Get Document From Pdf4me.
- Select your PDF4me credential, or create one and paste your API key.
- Set File Name to the exact stored name, ideally through an expression that carries it from the earlier step.
- Set Callback URL to a reachable endpoint. The node will not execute while it is empty.
- Execute the node.
- Check
successandretrievalCompletedin the response with an IF node. - Confirm
mimeTypematches what you expect before handing the file to a step that assumes a format. - Route the binary document to storage, email, or the next PDF4me action.
Typical Setups
Workflow ExamplesCommon n8n workflow patterns using Get Document From Pdf4me.
- An earlier action starts work on a large document.
- Get Document From Pdf4me collects the finished file by name.
- The workflow continues without holding a connection open.
- The stored file is retrieved unchanged.
- A second PDF4me action compresses or secures it.
- Retrieval and processing stay cleanly separated.
- A recipient asks for a document that was generated earlier.
- The workflow retrieves it by its stored name.
- It is emailed again without regenerating anything.
- An IF node checks success and retrievalCompleted.
- mimeType is compared against what the next step expects.
- A mismatch alerts instead of failing deeper in the chain.
Practical Tips
Cheat Sheet
| Field | Value |
|---|---|
| Action | Get Document From Pdf4me |
| File Name | document.pdf |
| Callback URL | https://example.com/callback |
| Credentials | PDF4ME account |
| Success check | success and retrievalCompleted |
| Format check | mimeType |