Extract Attachment From PDF in Make
Extract Attachment From PDF is a Make module that retrieves all files embedded inside a PDF document automatically within a scenario. It handles PDF portfolios, standard PDF attachments, and PDF/A-3 source files, returning each extracted file as a Base64-encoded item in an Attachments array ready for an Iterator to process individually.
The module returns all attachments as an array in a single output bundle. Add a Make Iterator module immediately after to split the array into individual bundles, one per attachment. Each bundle contains File Name and File Data (Base64) so you can route files to different destinations based on type or name.
Each extracted attachment is returned as a Base64 string in the File Data field. Most Make storage integrations (Google Drive, Dropbox, OneDrive) accept Base64 directly. If a downstream module requires binary input, convert using the Make toBinary(File Data, 'base64') function before mapping.
Beyond standard PDF attachments, this module handles PDF portfolios (multi-file containers) and PDF/A-3 archive documents with embedded source files. For PDF/A-3, the source files (Word, Excel, XML) are extracted while the archive PDF remains intact in compliance storage, per the PDF/A-3 specification.
Authenticating Your API Request
To access the PDF4me Web API through Make, every request must include proper authentication credentials. Authentication ensures secure communication between your Make scenarios and PDF4me's attachment extraction services.
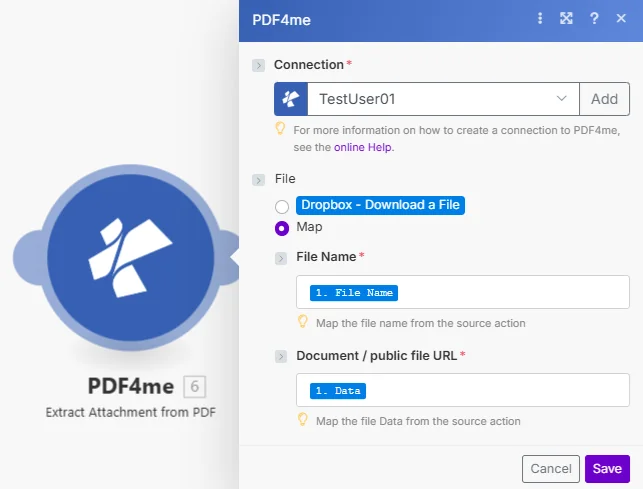
Map File Name and Document from the prior download step, then chain a Make Iterator to process each extracted attachment.
How to Set Up Extract Attachment From PDF in Make
- Add PDF4me > Extract Attachment From PDF to your scenario.
- Select your Connection or click Add to create one with your API key.
- Map File Name (with .pdf extension) from the prior module or enter a static name.
- Map Document (binary PDF buffer) from a Google Drive, Dropbox, email, or HTTP download step.
- Add a Make Iterator after this module and map it to the Attachments array output.
- Connect downstream modules to the Iterator output: upload to cloud storage, email, import data, or route by file type.
Parameters
| Parameter | Required | What it does | Example |
|---|---|---|---|
| File Name | Required | Filename of the source PDF including the .pdf extension. Map from the previous module's file name output or enter a static name. | portfolio.pdf |
| Document | Required | Binary PDF file content. Map from a Google Drive, Dropbox, email, or HTTP download step. The PDF must contain embedded attachments for the module to return results. | [PDF Buffer] |
Output
| Field | Type | What it contains |
|---|---|---|
Attachments | Array | Collection of all extracted attachment objects. Feed into a Make Iterator to process each file individually. |
File Name | String | Filename of the individual attachment including its extension (e.g. source_data.xlsx). |
File Data | Base64 | Content of the individual attachment encoded as Base64. Map to a storage upload module or decode with toBinary() for modules that require binary input. |
What File Types Can You Extract From a PDF?
Any file type embedded as an attachment is supported: spreadsheets (XLSX, CSV), Word documents (DOCX), images (PNG, JPG), ZIPs, or other PDFs. This includes files in PDF portfolios (Adobe's multi-file container format) and source files embedded in PDF/A-3 archives per the ISO 19005-3 standard. The module preserves original file formats and extensions in the returned File Name field.
Workflow Examples
- Compliance Extraction
- PDF/A Source Recovery
- Portfolio Distribution
Extract and organize evidence files from compliance submission PDFs
- Trigger: Compliance submission PDF received (email attachment or Watch Folder)
- Download PDF: Retrieve the compliance package
- Extract Attachments: Retrieve all embedded evidence files
- Iterator: Process each extracted attachment individually
- Classify by extension: Route to appropriate compliance folder (spreadsheets, images, docs)
- Upload: Save each file to the correct folder in SharePoint or Google Drive
- Log: Record all extracted files in a compliance database
- Notify team: Alert compliance team of processed submission
Retrieve editable source files from PDF/A-3 archive documents
- Trigger: PDF/A-3 archive document needs its embedded source file
- Download Archive PDF: Retrieve the PDF/A-3 document from compliance storage
- Extract Attachments: Retrieve the embedded Excel or Word source file
- Validate: Confirm extracted file is complete
- Upload Source File: Save to an editable files folder
- Notify requester: Send extracted source file link
Unpack PDF portfolios and distribute files to the right teams
- Trigger: PDF portfolio received from client
- Download Portfolio: Retrieve the portfolio PDF
- Extract All Attachments: Retrieve all embedded files
- Iterator: Process each extracted file
- Route by file type: Send each file to the appropriate team folder
- Email individually: Deliver each file to the designated recipient
- Confirm: Notify sender that portfolio was processed and distributed